Job dependencies
Quite often a computational analysis job consists of clearly separable steps with very different computational requirements. Consider for instance an analysis jobs that periodically searches the web for news articles, and then runs some machine learning pipeline over the collected data. This process requires
- fast internet access for the fetching data from the web, and
- a GPU server to run the machine learning pipeline.
If both stage run on the GPU server, the GPUs will be idle during the data fetching face wasting valuable resources.
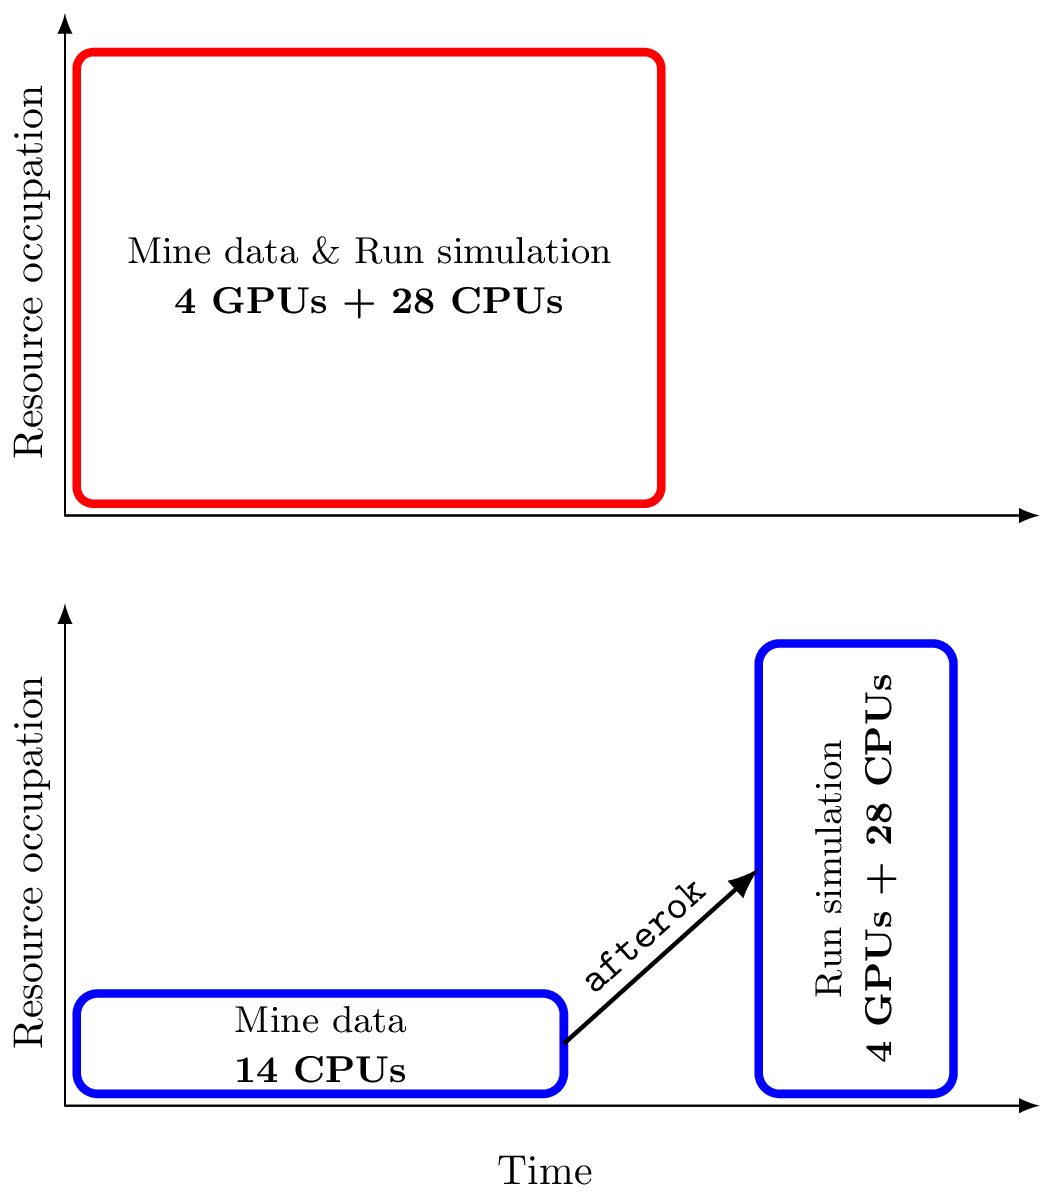
The solution is to split the job into 2 smaller jobs,
- one job for the data fetching that will run in a few cores of a CPU node, and
- one job for the machine learning pipeline that with use the data fetched and that will run on a GPU node.
Slurm provides the mechanism of job dependencies to orchestrate complex collections of interdependent jobs.
Specifying job dependencies
Job dependencies are declared with the --dependency (-d in short format) option flag.
$ sbatch --dependency=<dependency_list> script.sh
The <dependency_list> object is composed by a number of dependencies in a comma (,) separated list
<dependency_list> = <dependency>[,<dependency>...]
?) separated list
<dependency_list> = <dependency>[?<dependency>...]
When a job with dependencies is queued, the job is not considered for execution until its dependencies are satisfied. The scheduler takes into account the end time of dependencies to reserve resources for depended jobs.
Job dependencies
| Dependency | Description |
|---|---|
after:job_id[+time][:jobid[+time]...] |
Enable after the listed jobs start or are canceled; wait time minutes before starting, start imediatelly if no time is specified). |
afterany:job_id[:jobid...][1] |
Enable after the specified jobs have terminated. |
afterburstbuffer:job_id[:jobid...] |
Enable after the specified jobs have terminated and any associated burst buffer stage out operations have completed. |
afternotok:job_id[:jobid...] |
Enable after the specified jobs have terminated in some failed state (non-zero exit code, node failure, timed out, etc). |
afterok:job_id[:jobid...] |
Enable after the specified jobs have successfully executed (ran to completion with an exit code of zero). |
singleton |
Enable after any previously launched jobs sharing the same job name and user have terminated. In other words, only one job by that name and owned by that user can be running or suspended at any point in time. |
aftercorr:job_id[:jobid...][2] |
Enable after the corresponding task ID in job_id array has completed successfully (ran to completion with an exit code of zero). |
- The default dependency type.
- Applicable only to job arrays.
Submitting jobs with dependencies
For instance, is you want second_job.sh to start after first_job.sh has completed successfully, then issue the commands:
$ first_job_id=$(sbatch --parsable first_job,sh)
$ sbatch --dependency=afterok:${first_job_id} second_job.sh
If you want dependant_job.sh to start after job_0.sh and job_1.sh have completed successfully, then issue the commands:
$ job_0_id=$(sbatch --parsable job_0.sh)
$ job_1_id=$(sbatch --parsable job_1.sh)
$ sbatch --dependency=afterok:${job_0_id},afterok:${job_1_id} dependant_job.sh
As the number of dependent job increases, it's more convenient to create a submission script with all the dependency information. For instance:
Contents of submit_jobs.sh
#!/bin/bash --login

declare copy_job_id=$(sbatch --parsable copy_data.sh)
declare analysis_job_0_id=$(sbatch --parsable --dependency=afterok:${copy_job_id} analysis_job_0.sh)
declare analysis_job_1_id=$(sbatch --parsable --dependency=afterok:${copy_job_id} analysis_job_1.sh)
sbatch --dependency=afterok:${analysis_job_0_id},${analysis_job_1_id} cleanup_job.sh
Then all jobs are submitted with one command:
$ bash submit_jobs.sh
The --parsable option of sbatch
With the option --parsable the sbatch command return a single string with the job ID that can be stored in a shell variable. For instance without --parsable, the output of the batch submission is
$ sbatch job.sh
Submitted batch job 12345
--parsable the output is
$ sbatch --parsable job.sh
12345